FAQPage markup no longer earns most sites a rich result. Google restricted FAQ rich results to well-known government and health sites in 2023, and for everybody else the visible reward simply went away. The markup is still valid and still parsed. It just has to justify itself on different grounds now.
Which is a useful thing to have happened, because the rich result was always the wrong reason to be using it.
What actually changed
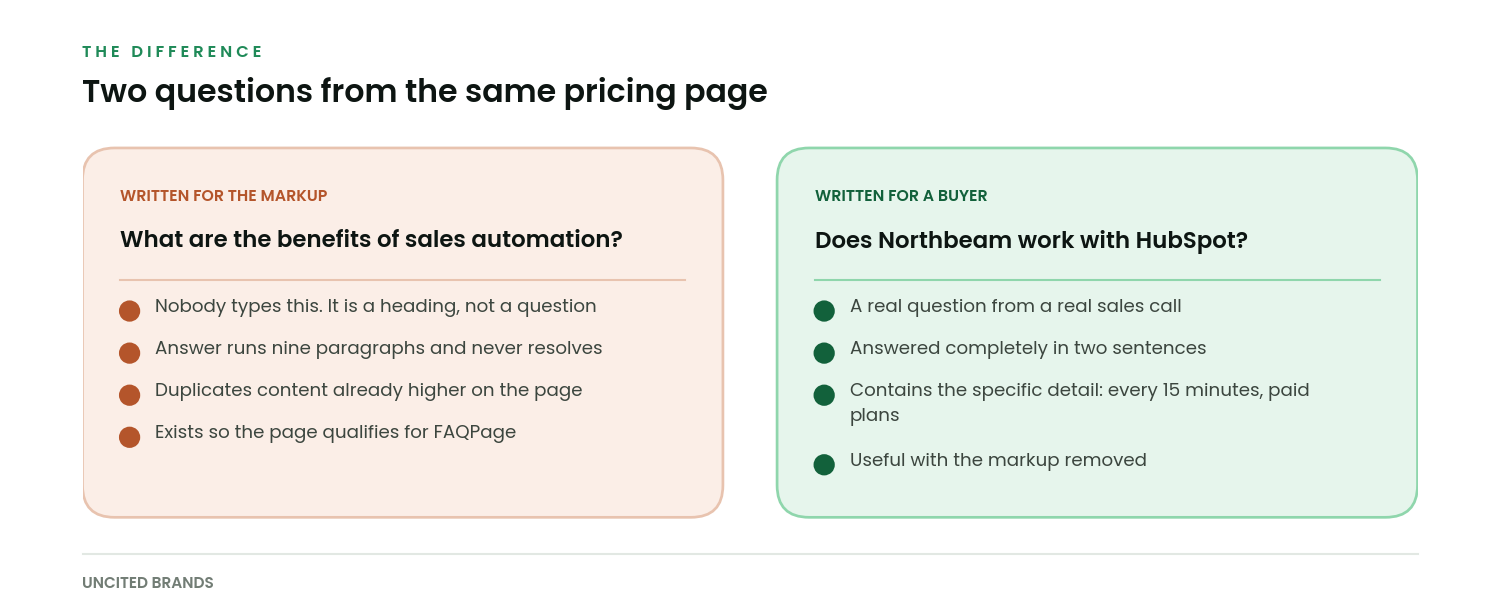
For several years FAQPage was the cheapest structured data win available. Add a few questions to the bottom of a page, mark them up, take two extra lines of search results. The incentive was obvious and the result was predictable. Pages grew question sections that no human had asked for, written backwards from the markup rather than forwards from a buyer.
Google withdrew the feature for most sites and documented the change in its structured data reference, which still describes the markup while noting who is eligible for the visual treatment. The markup did not become invalid. The arbitrage closed.
The part worth keeping. Writing a page as a set of real questions with complete answers is a genuinely good habit for AI retrieval. Doing it to qualify for a badge was always the tail wagging the dog.
The one test
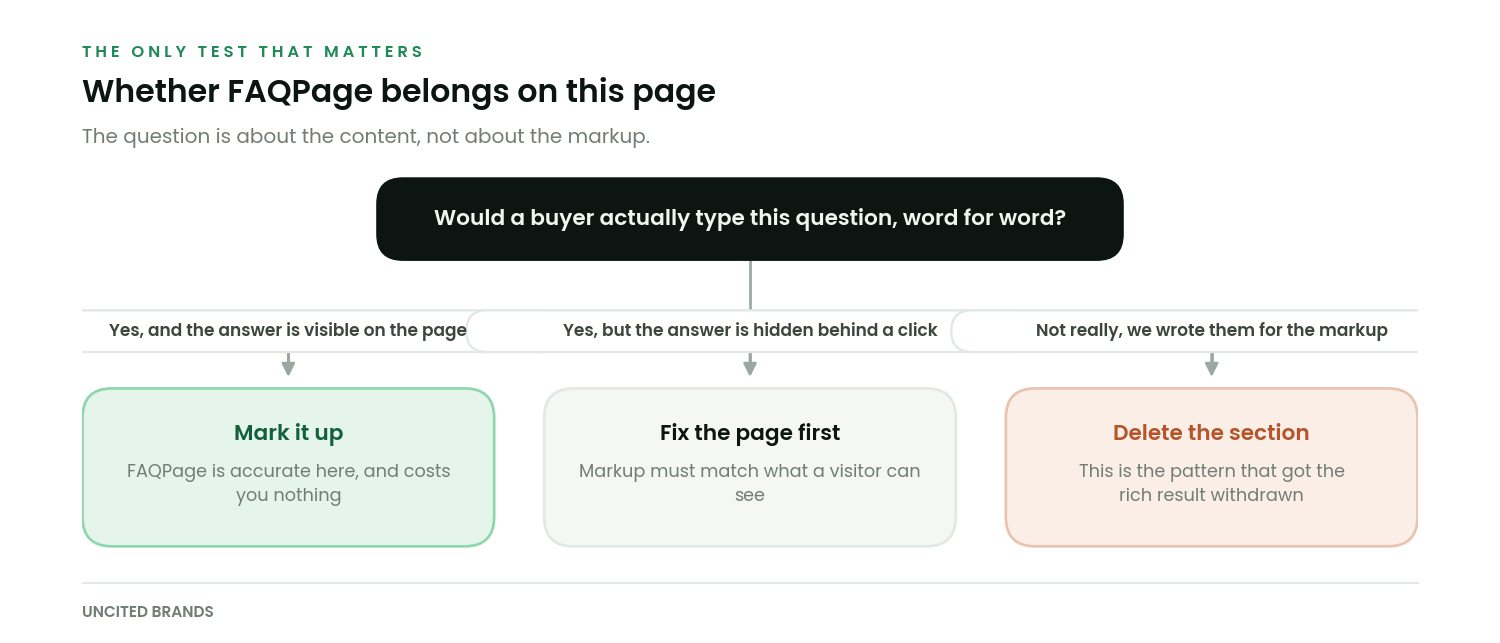
Everything below is commentary on that diagram. If a buyer would type the question in those words, and the answer is visible on the page without clicking anything, the markup is accurate and you may as well have it. Any other situation is a content problem that markup cannot fix.
Why it matters for answer engines, which is a different question
Retrieval systems break pages into chunks and match chunks against a question. A question heading followed by a complete two or three sentence answer is close to an ideal chunk. It is self-contained, it states the subject explicitly rather than relying on a pronoun pointing at a previous paragraph, and it ends where the answer ends.
That shape helps whether or not you add any markup at all. The markup is a secondary confirmation of a structure the text already has. This is the same argument as answer-first writing, applied to a smaller unit.
What does not help is the thing the old incentive produced. A question with a nine paragraph answer that wanders into three other topics is a worse chunk than a plain heading would have been, because the retrievable unit now contains mostly irrelevant text.
The rules the markup still has to follow
| Rule | Why it exists | What breaks if you ignore it |
|---|---|---|
| Answer text must be visible on the page | Markup describes the page, it does not extend it | Mismatch between markup and content, which is a policy violation |
| Content behind an accordion counts as visible | Collapsed is not the same as absent | Nothing, as long as the text is in the HTML at load |
| Content loaded only after a click does not count | A crawler does not click | Your markup describes text no crawler ever receives |
| One FAQPage per page | Two FAQPage items describe two pages | Parsers resolve it unpredictably, often by ignoring both |
| No promotional text in the answer | An answer is an answer, not a pitch | The markup is still valid and the chunk retrieves badly |
| Questions should be unique across your site | Twelve pages answering the same question compete with each other | You split your own retrieval across near-duplicates |
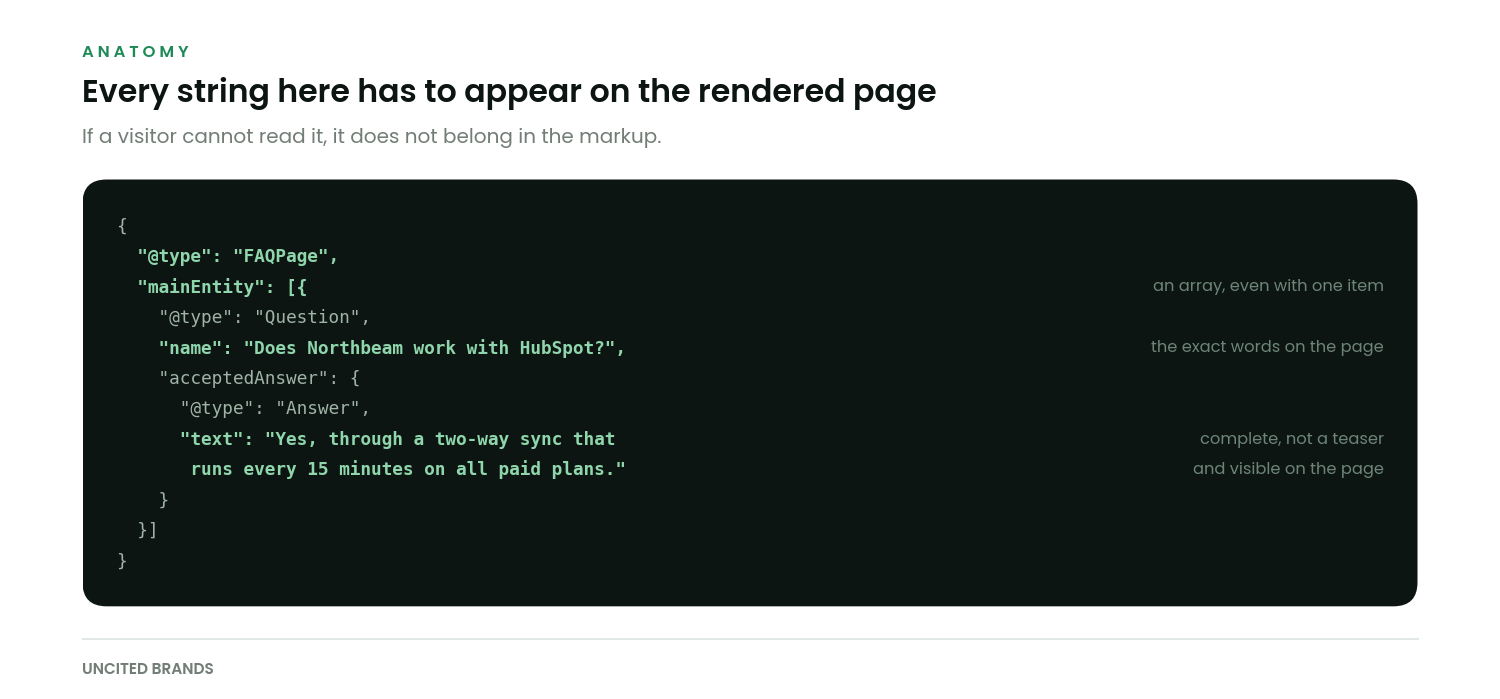
On the accordion question, which comes up every time. Content inside a collapsed details element is present in the HTML and counts as visible. Content fetched by JavaScript when the user expands a panel is not present, and marking it up is a mismatch. The HTML specification for interactive elements is clear about what details does, and it is the simplest way to build an FAQ that is both collapsible and fully crawlable.
<!-- crawlable: the text is in the HTML at load -->
<details>
  <summary>Does Northbeam work with HubSpot?</summary>
  <p>Yes, through a two-way sync that runs every 15 minutes
     on all paid plans.</p>
</details>

<!-- not crawlable: the answer does not exist until a click -->
<div class="faq" data-answer-url="/api/faq/17">
  <button>Does Northbeam work with HubSpot?</button>
</div>
If you do build a custom disclosure widget rather than using details, the W3C disclosure pattern gives you the keyboard and screen reader behaviour you are otherwise going to get wrong. Accessible markup and crawlable markup turn out to be the same markup most of the time.
Where FAQ sections genuinely belong
Three places, in our experience, and they are all places where the questions existed before the page did.
- Pricing pages. Buyers arrive with objections and they are always the same six. Answering them in plain words is the highest-value FAQ content on most SaaS sites, which is part of why the pricing page matters so much.
- Integration and compatibility pages. Does it work with X. Real question, binary answer, enormous search volume, and almost nobody answers it in the first sentence.
- Security and compliance pages. Where is data stored, which certifications, who has access. Procurement asks these in a fixed order and you can simply publish the order.
Where they do not belong is the bottom of a blog post, bolted on after the fact. If the article did not answer the question in its body, a stub at the end will not either. If it did, the stub is a near-duplicate competing with the original passage for retrieval.
What to do with the FAQ sections you already have
Read them as a stranger. For each question, ask whether anybody has ever said that sentence out loud to your sales team. Keep the ones that pass, rewrite the answers so each is complete in two or three sentences without needing the rest of the page, and delete the rest. Then decide about markup, which will take about ten minutes and matters far less than the previous step.
Usability research on FAQ pages has been consistent for a long time that people scan for their specific question and abandon quickly when the list is padded. The Nielsen Norman Group archive covers this under information scent. A retrieval system behaves similarly for different reasons, which is a convenient coincidence. Short, real, specific wins twice.
Related reading
- Schema markup for AEO. Which types are worth the effort, ranked honestly.
- Product or SoftwareApplication. The type decision that matters considerably more than this one.
- Organization schema. The company-level markup everything else should point at.
- The glossary page. A better home for definitional questions than an FAQ block.
Delete more than you mark up.
On almost every site we audit, the right move on FAQ sections is subtraction. Four real questions answered properly will do more for you than fourteen written to fill a schema requirement that no longer pays out.
We publish one short piece a week on this sort of thing, usually with the test behind it. Subscribe if you want them.
Shaban runs answer engine optimisation for B2B SaaS companies at Uncited Brands. He works the unglamorous end of the problem, mostly crawler access, retrieval diagnostics and measurement baselines, and publishes the tests that do not go his way alongside the ones that do.