An AI answer about sales software names four vendors. The category contains several thousand. The cut from several thousand to four happens in three passes, and only the second has much to do with whether your product is any good.
That sounds bleak and it is actually the opposite. Two of the three passes are about how clearly you are described rather than how well you perform, and description is something you control completely.
First, see how short the list really is
We ran forty questions a sales software buyer would plausibly ask, twice each, across four engines. The question set was fixed before the first run and no question named a vendor.
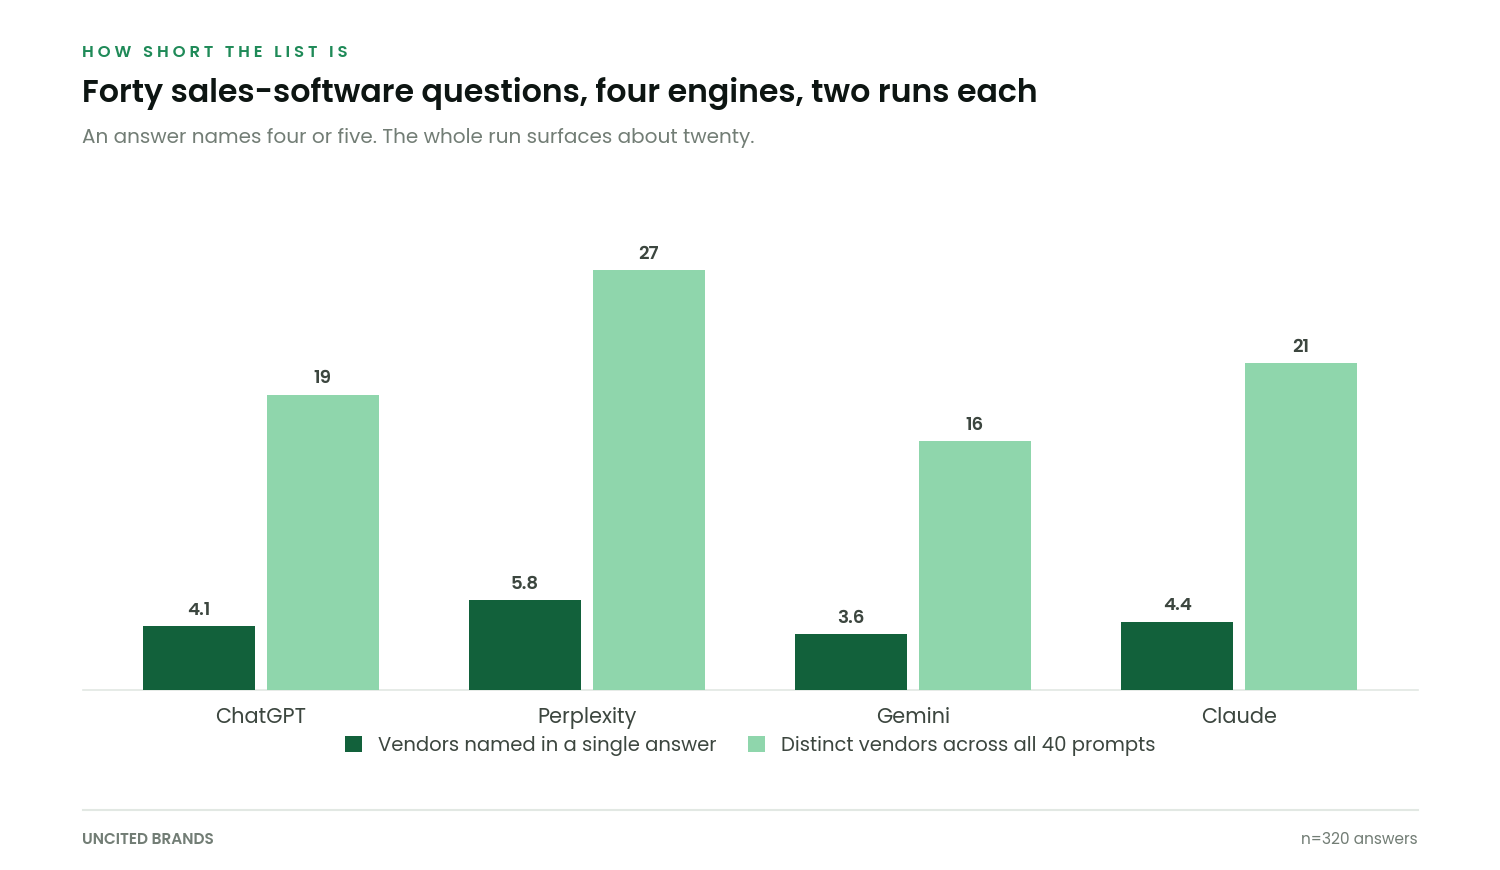
Two numbers matter here. A single answer names four or five vendors, which is roughly the size of a human shortlist and is probably not a coincidence. The whole run across forty varied questions surfaced about twenty distinct names. Twenty. In a category where a directory will happily list nine hundred.
The useful way to read that. The second number is the real prize. You do not need to win the one question about the best sales tool. You need to be one of the twenty that the engine considers a legitimate answer to anything in the category.
The three cuts, in order
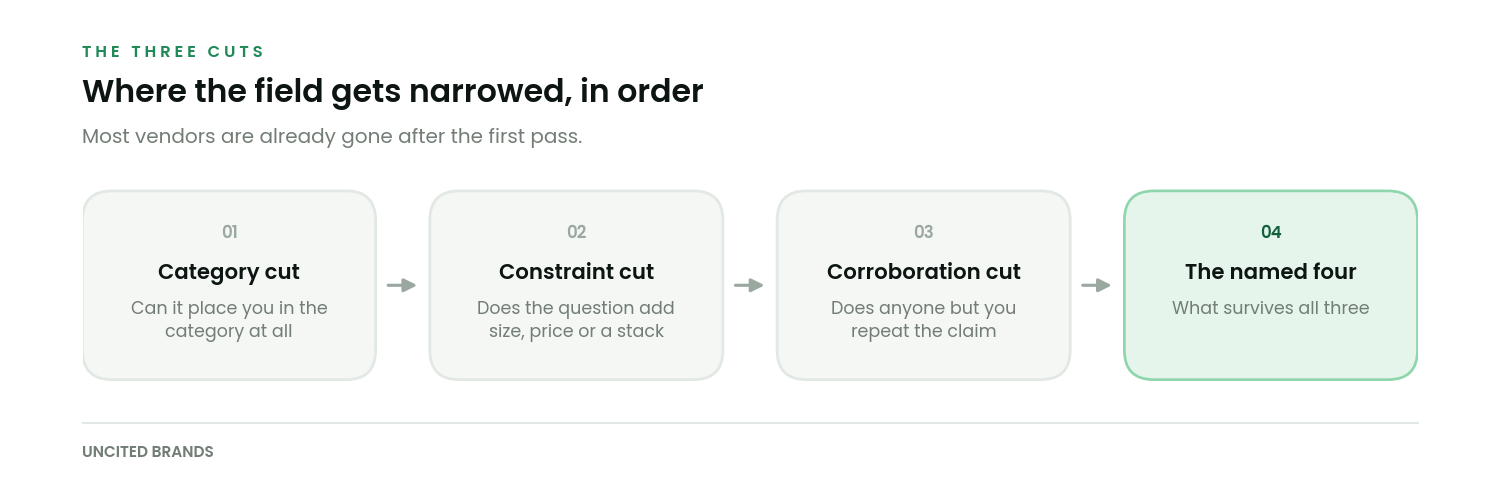
The category cut. Before an engine weighs anything it has to decide what you are. This is the pass almost everyone fails and almost nobody measures. If your homepage says revenue acceleration platform, your documentation says sales engagement, your pricing page says CRM and your directory listing says lead management, you have given four answers to one question. A system picking four names from a thousand will not spend its confidence on the vendor it cannot place.
Category confusion is not a branding problem. It is a retrieval problem, and it has a measurable shape. We wrote about how to tell the two apart in retrieval problem or reputation problem, which is worth reading before you blame your product.
The constraint cut. This is the only pass where product fit does the work. A question that adds a constraint, such as a team size, a budget ceiling, a required integration or an industry, collapses the candidate set hard. Broad questions have many defensible answers and the engine falls back on the most familiar names. Constrained questions have few, and familiarity stops being enough.
This is where smaller vendors win, and it is why what buyers actually ask is more useful to you than any keyword list. Real questions carry constraints. Keyword tools strip them out.
Want to see which of the three cuts is dropping you?
The free check runs a fixed question set against your category and tells you whether you are being dropped at the category pass, the constraint pass or the corroboration pass. Those three problems need completely different work. Run the check.
The corroboration cut. Among candidates that survive the first two passes, engines prefer the ones whose claims appear somewhere other than the claimant. This is not a popularity contest. It is a cheap reliability heuristic, and it is the same one a sensible buyer uses.
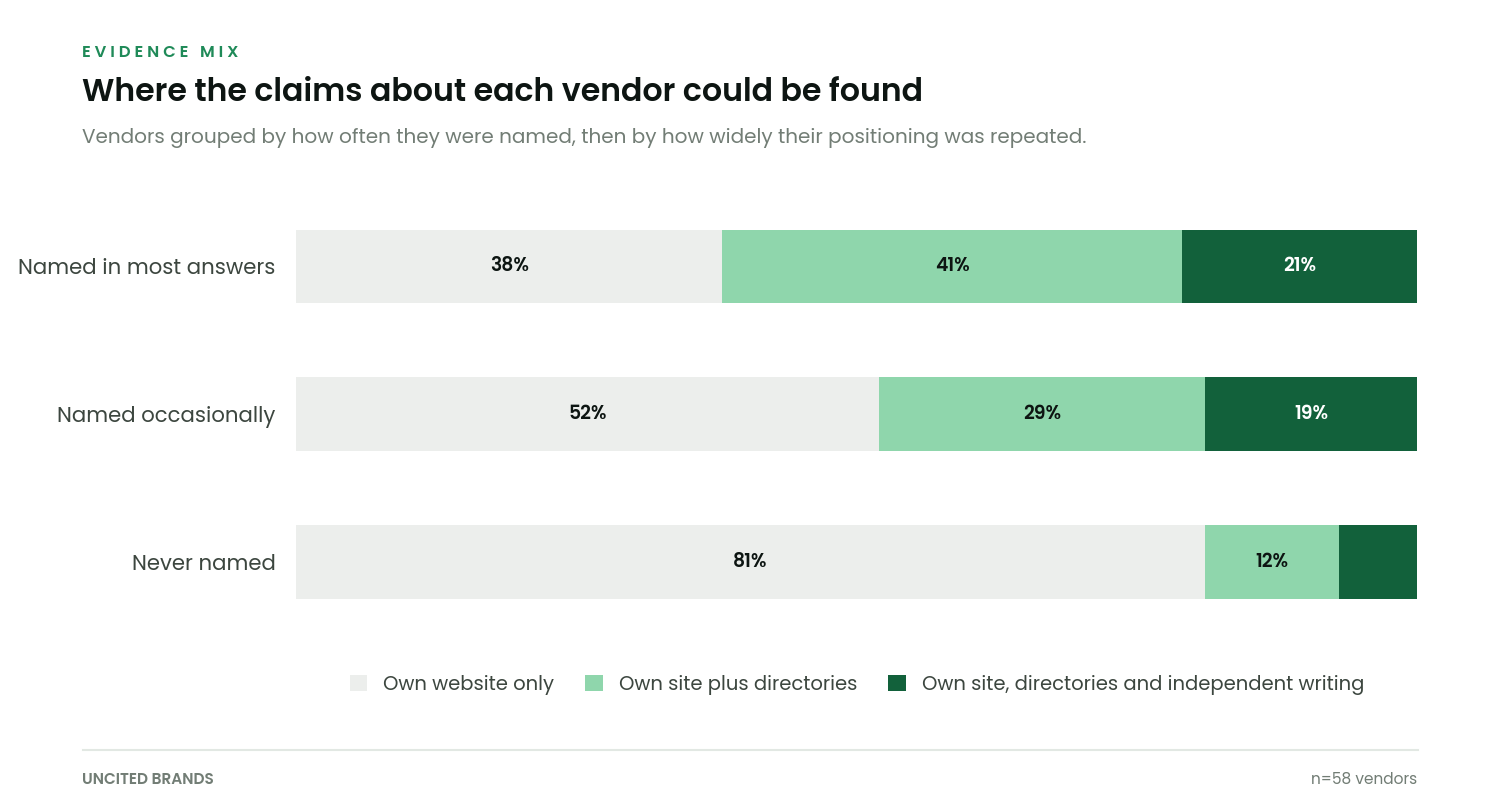
The pattern in that chart is the whole argument of this piece. Vendors who are never named are overwhelmingly vendors whose positioning exists only on their own website. Vendors named in most answers have the same description of themselves turning up in directories, in documentation written by their integration partners and in writing by people who do not work for them.
Why the category keeps getting more crowded and the answer does not
Category entry has got cheaper every year. Being confidently placed in a category has not. That gap is the whole story.
There is a long tradition in marketing measurement arguing that buyers choose from a small set of options that come to mind rather than evaluating a market, and that the size of that set is stubbornly small regardless of how many options exist. The work from the Ehrenberg-Bass Institute on mental availability is the clearest version of it. An engine building a four name answer is doing mechanically what a buyer does from memory, with one difference that favours you. Its memory is rebuildable.
The mechanism is retrieval rather than recall. Current systems fetch candidate documents at question time and compose an answer over them, the approach described in the original retrieval-augmented generation paper and refined heavily since. That is good news. Recall takes years to change. What gets retrieved can change in a quarter, and the difference between the two determines how fast anything you do will show up.
| Cut | What it is really testing | What moves it | How long it takes |
|---|---|---|---|
| Category | Can you be placed with confidence | One description of yourself, repeated everywhere without variation | Weeks |
| Constraint | Do you fit the specific case named | Pages that answer constrained questions directly, in plain words | Weeks to months |
| Corroboration | Does anyone but you say it | Directory accuracy, partner documentation, independent writing | Months |
| Familiarity | Have you been written about for years | Mostly time, and it matters less than vendors assume | Years |
What to do about it, in order
- Write the category sentence. One sentence that names the category in the words buyers use, not the words your positioning deck uses. Not a tagline.
- Make everything agree with it. Homepage, documentation, pricing page, schema markup, every directory listing, your own LinkedIn description. Variation here is the expensive kind.
- Answer constrained questions on their own pages. One page per real buyer constraint, answering it in the first two sentences rather than the eighth paragraph.
- Fix the directories you have been ignoring. Outdated category tags on review sites are repeated by engines with a confidence the listing does not deserve. Much of what feeds model training comes from broad public crawls such as Common Crawl, which means a stale listing can outlive the correction by a long time.
- Then measure, with a fixed question set. Not mentions. Named appearances against a set you wrote before you looked at any results.
On that last point, the metric worth tracking is share of model, and it is only meaningful under a published method. Analysts spend a lot of energy arguing about where category boundaries sit, and firms like Gartner redraw them regularly. You do not have to win that argument. You have to pick one answer and stop contradicting yourself.
The category cut is unglamorous and it is where the money is.
Nearly every vendor we audit is spending on the constraint cut, writing comparison pages and feature content, while failing the category cut on their own homepage. That order is backwards and it is expensive.
An audit tells you which pass is dropping you and what the fix costs in hours. Book one here, or take the method from this page and run it yourself.
The uncomfortable part
Some of this is not winnable in the time you have. If your category has four incumbents with fifteen years of independent writing about them, you are not going to displace them on the broad question this quarter. Anyone promising otherwise is selling you something.
What is winnable is the twenty. Being a name an engine considers legitimate for the category, and then being the obvious answer to the constrained questions where the incumbents are a poor fit. That is a real position and it converts better than the broad one anyway, because the buyer asking a constrained question is much further along than the buyer asking which tool is best.
Related reading
- AI visibility for sales and marketing SaaS. The wider playbook this cut sits inside.
- What buyers actually ask. The real questions, with the constraints left in.
- How Perplexity chooses sources. Why one engine names twice as many vendors as another.
- What AEO is. Start here if this is the first piece of ours you have read.
Four names, chosen in three passes, two of which are about description.
That is the whole mechanism. It is not mysterious and it is not rigged, and the work it rewards is the work most marketing teams consider beneath them.
If you want to know which pass is costing you, the free visibility check will tell you in about a day, and you keep the output either way.
Shaban runs answer engine optimisation for B2B SaaS companies at Uncited Brands. He works the unglamorous end of the problem, mostly crawler access, retrieval diagnostics and measurement baselines, and publishes the tests that do not go his way alongside the ones that do.