Every AEO case study you will ever be shown was produced by the party who benefits from it, selected from a pool whose failures were never written up, and measured by a method you cannot inspect. Ours included.
That is not an accusation. It is the structure of the thing, and it applies to every agency in every discipline. What follows is how to read them anyway, which turns out to be straightforward once you stop reading them for the result.
The result was never the evidence
A case study headline is an outcome. Outcomes in this field are produced by the work, the client, the category, the competition, the engines changing underneath everybody, and whatever else the client happened to do that quarter. Attributing the whole movement to the agency is not usually a lie. It is just not a claim anybody has the data to make.
The method, on the other hand, is checkable. And an agency that ran a real method on one client will run it on you, while an agency that produced a number after the fact will produce another one after the fact.
Read case studies the way you would read a study. Nobody sensible reads a clinical paper by skipping to the conclusion. The conclusion is the least informative part, because it is the part most shaped by whoever wrote it.
The same engagement, written two ways
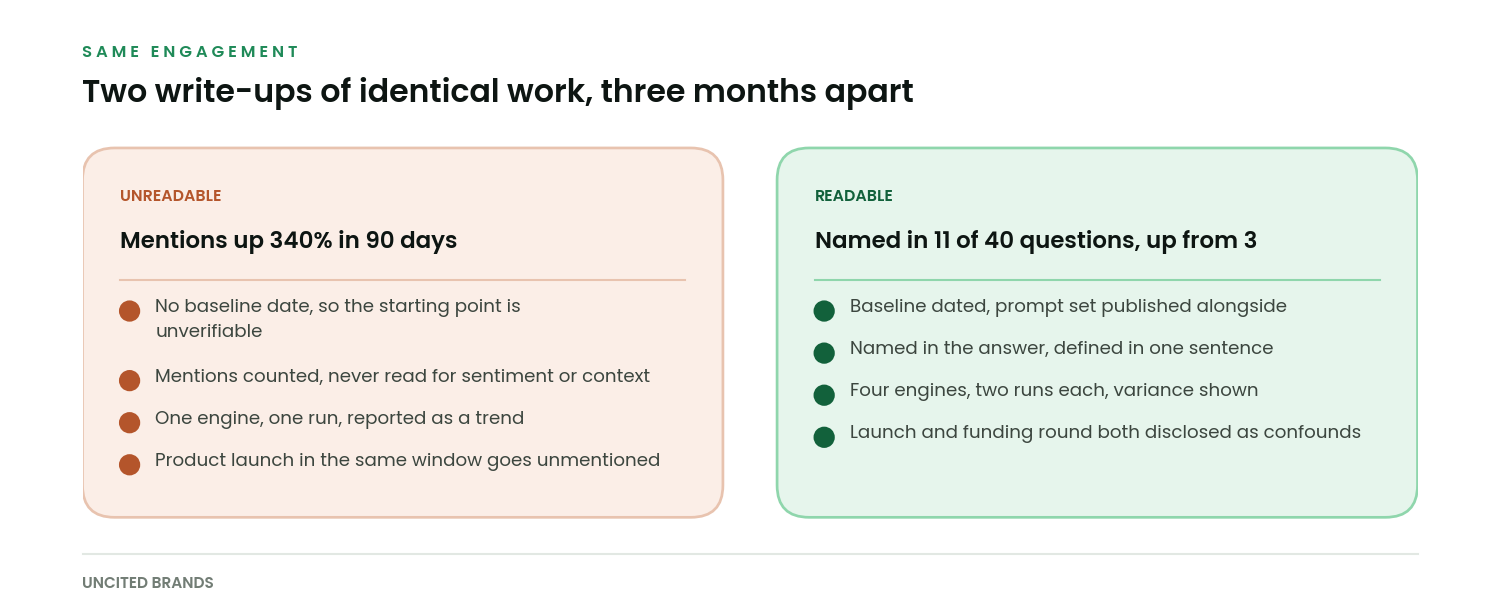
The left-hand version is not fabricated. Mentions genuinely rose by three hundred and forty percent, from five to twenty two, across one engine, in a quarter when the client also announced a funding round and shipped a product that got written about. All of that is true and none of it tells you whether to hire anybody.
The right-hand version has a smaller headline and is worth something. Eleven of forty, up from three, with the forty questions available to read. You can judge whether those questions resemble the ones your buyers ask. You can see the confounds you were not shown on the left.
If you have case studies in front of you right now and want a second read, send them over. We will tell you which claims are checkable and which are presentation, including when the answer is that they look fine. Book twenty minutes.
Six questions
In rough order of how much they tell you per second spent asking.
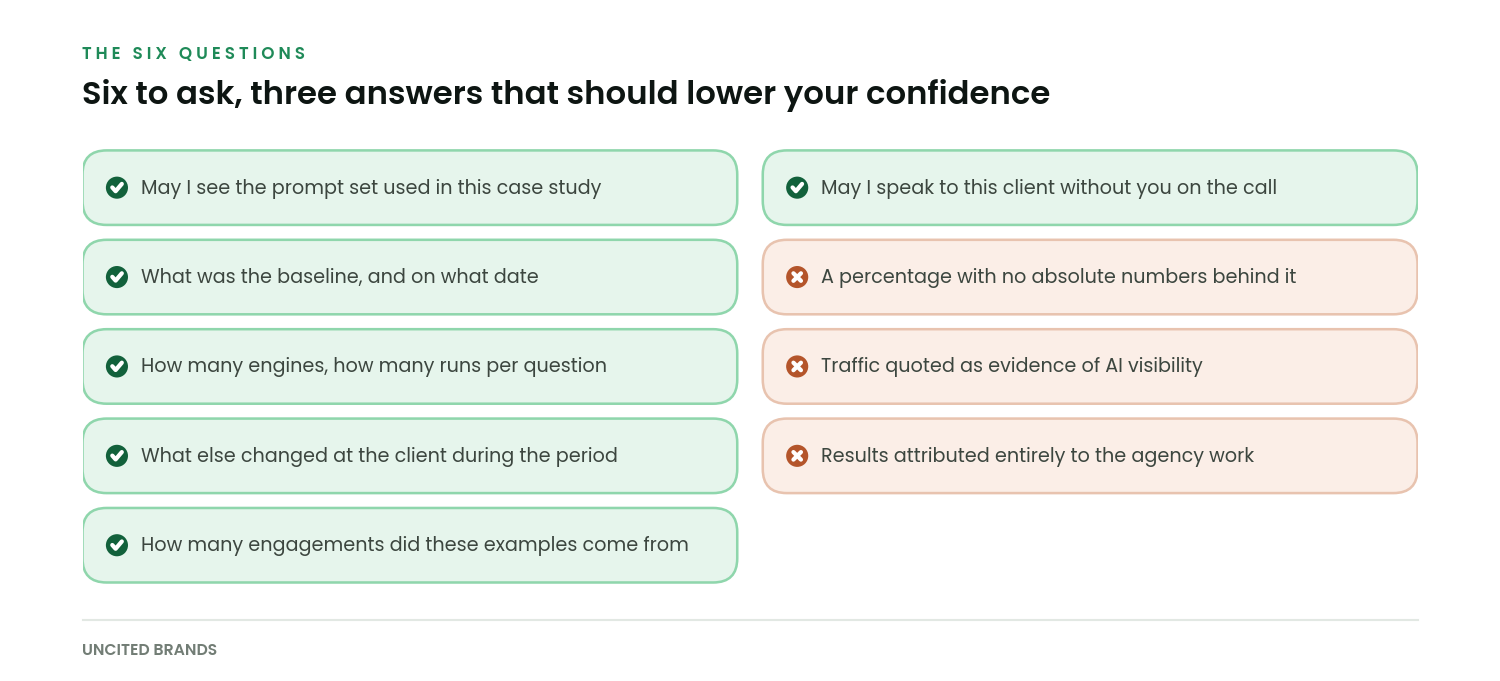
- May I see the prompt set? If it exists and is dated, almost everything else follows. If it was assembled after the results came in, every number downstream is unfalsifiable.
- What was the baseline, and on what date? A baseline without a date is a screenshot. The date also lets you check what else was happening to that company.
- How many engines, how many runs? One run per question on one engine is a sample of one. These systems vary between runs by design, so a single-run comparison measures variance as often as it measures change.
- What else changed at the client? Funding, a launch, a rebrand, a big partnership, a competitor failing. Any of these moves citation numbers more than most optimisation work does. An honest write-up names them.
- How many engagements were these selected from? The question nobody asks. Three case studies from four clients is a very different claim from three case studies from forty.
- May I speak to the client without you present? The answer is informative regardless of what the client then says.
Three numbers that mean nothing on their own
| The number | Why it is quoted | What it hides |
|---|---|---|
| Mentions up X percent | Percentages from a small base look enormous | The base. Five to twenty two is 340 percent and is also seventeen mentions |
| Visibility score up X points | It is their score, so it is always available | The weights, which can be changed, and which you cannot reproduce |
| Organic traffic up X percent | It is easy to measure and the client already has it | That AI citation and search traffic are different channels moving for different reasons |
| Ranked first in ChatGPT | It sounds like a position and there are no positions | The prompt, the date, the run count and whether it held |
| Sentiment improved | Every tool now reports it | The classifier, its accuracy on your category, and the sample size |
The percentage problem deserves one more line because it is the most common. Any metric with a small base produces spectacular percentages, and AI citation counts always start small. Insisting on absolute numbers alongside every percentage removes most of the theatre at no cost to anybody honest.
The survivorship problem, which nobody mentions
Case studies are drawn from engagements that went well enough to publish. An agency that succeeds three times in ten and an agency that succeeds nine times in ten produce case study pages that look identical, because both publish their three best.
There is no clean fix for this and there is a partial one. Ask for the denominator. Ask what a disappointing engagement looked like and what they changed afterwards. The answer tells you whether failures are examined or filed. Research practice has spent decades on exactly this problem, which is why trial registration exists and why groups like the EQUATOR Network publish reporting standards that require studies to be declared before results are known.
Nobody is going to pre-register an agency engagement. The transferable part is smaller and still useful. The prompt set is the protocol, and asking to see it dated before the first run is the marketing equivalent of asking whether the study was registered.
We publish the tests that went against us, and it costs us work.
A case study where the changes produced no measurable movement is not a good sales asset. It is the most informative thing we can show you, because it tells you what we do when the plan does not work, which is the situation you are actually buying insurance against.
If you want a baseline built under a method you can inspect and keep, book an audit. The output is yours whether or not we go further.
What to weigh instead
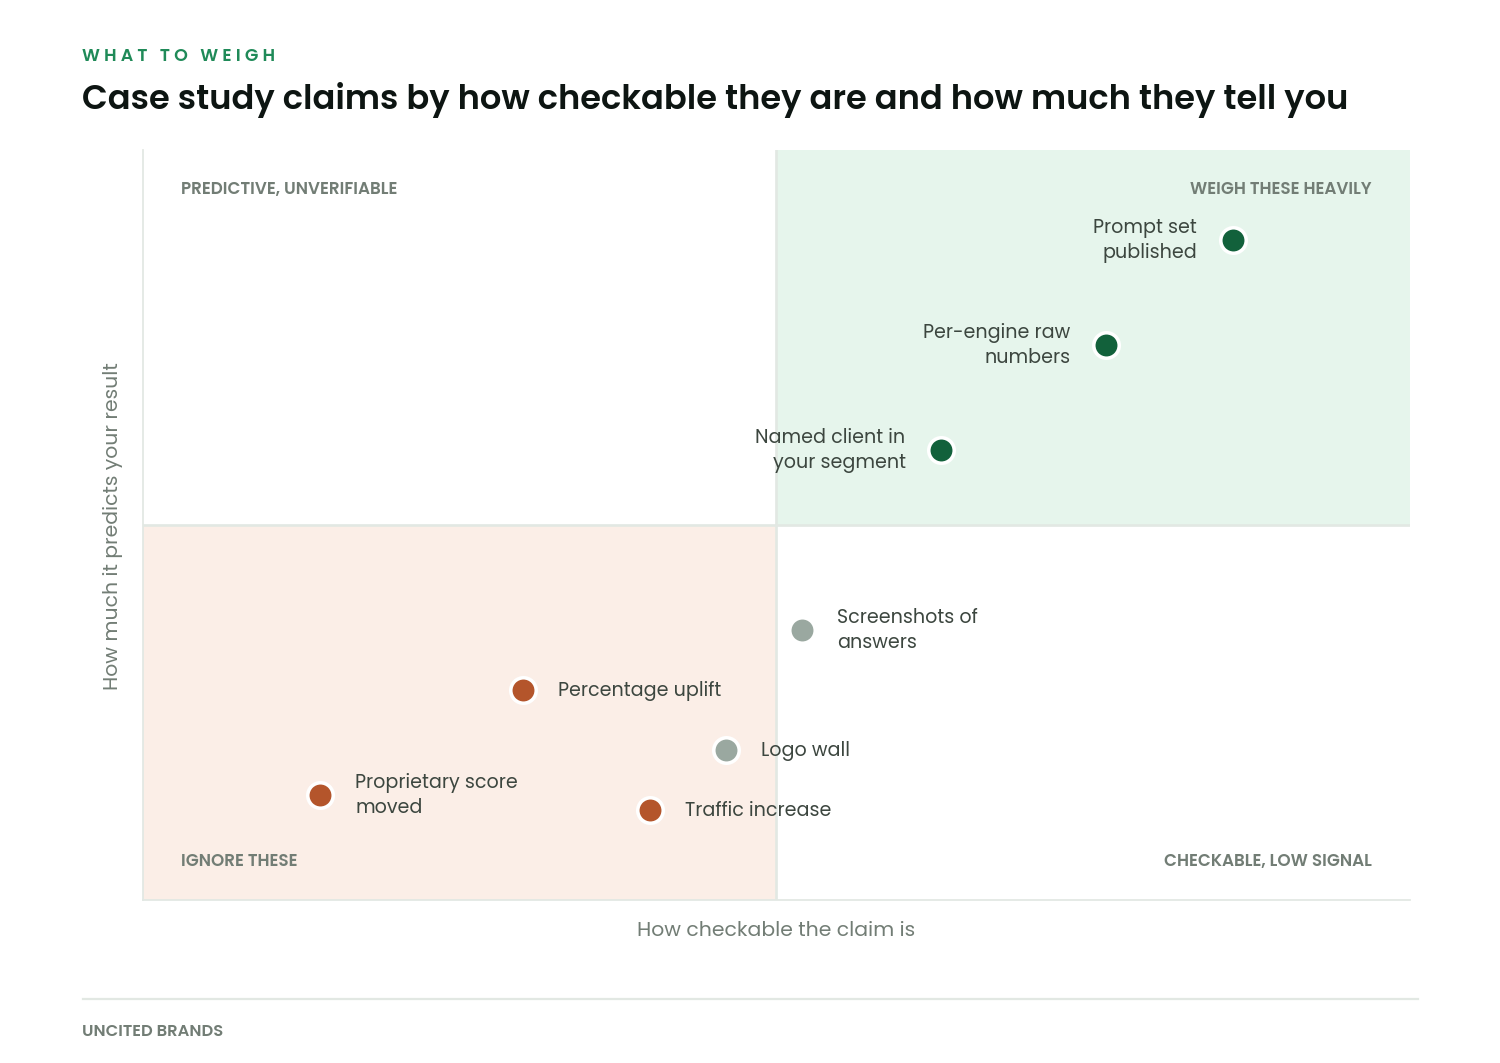
The strongest signal in any case study is a named client in your segment with a method you can read. The second strongest is a disclosed confound, because volunteering the thing that weakens your own claim is expensive and nobody does it by accident.
The weakest signals are the ones that dominate most pages. Logo walls tell you who paid, not what happened. Screenshots of answers tell you what one run returned on one day. Percentage uplifts tell you about the base, which you were not shown.
A note on reproducibility, since it is the real issue
Large reproducibility surveys across the sciences have repeatedly found that most researchers have failed to reproduce someone else’s result, and a majority have failed to reproduce their own. Nature has published several of the better-known ones. If that is the state of fields with peer review, registration and professional incentives toward accuracy, you should calibrate your expectations for a discipline that has none of those things and is four years old.
Disclosure norms are the other half. Medical publishing requires competing interests to be declared, under rules maintained by bodies like the ICMJE, precisely because the reader cannot otherwise weigh the result. A marketing case study is one hundred percent competing interest by construction. Treating it as such is not cynicism, it is just reading it correctly.
And evidence hierarchies are worth borrowing. Organisations like Cochrane rank evidence by how well the design controls for the ways people fool themselves. A single uncontrolled before-and-after comparison, reported by the party who made the change, sits near the bottom of every such hierarchy ever drawn. That is what an agency case study is, and it is still better than nothing when the method is visible.
What this means practically
Do not discard case studies. Downgrade them. Treat them as evidence about process rather than evidence about outcome, weight them below a reference call you arranged yourself, and weight everything below a small paid pilot where you set the measurement.
That last option is underused. A four week diagnostic with a prompt set you approve is cheaper than a bad six month retainer by an order of magnitude, and it generates evidence about your category rather than about someone else. The pricing piece covers what that should cost.
Related reading
- Red flags in an AEO pitch. The companion piece, aimed at the proposal rather than the case study.
- The buyer’s guide. The full selection process, start to finish.
- Twelve questions to ask. What to put to them on the call itself.
- Our methodology. The protocol we are asking you to hold other people to.
Ask for the prompt set and the denominator. Those two questions do most of the work.
One tells you whether a method existed. The other tells you how many attempts the examples were chosen from. Almost nobody asks the second one, and the reaction to it is frequently more informative than the answer.
If you would rather have a baseline built on your own category than read about another company, that is what the audit is.
Shaban runs answer engine optimisation for B2B SaaS companies at Uncited Brands. He works the unglamorous end of the problem, mostly crawler access, retrieval diagnostics and measurement baselines, and publishes the tests that do not go his way alongside the ones that do.